How to keep characters, products and logos consistent in AI video
AI draws a new face every time it is asked. Your film needs the same face, product and logo in shot 1 and shot 40. This is how that gap is closed, and the one question to ask before you start.
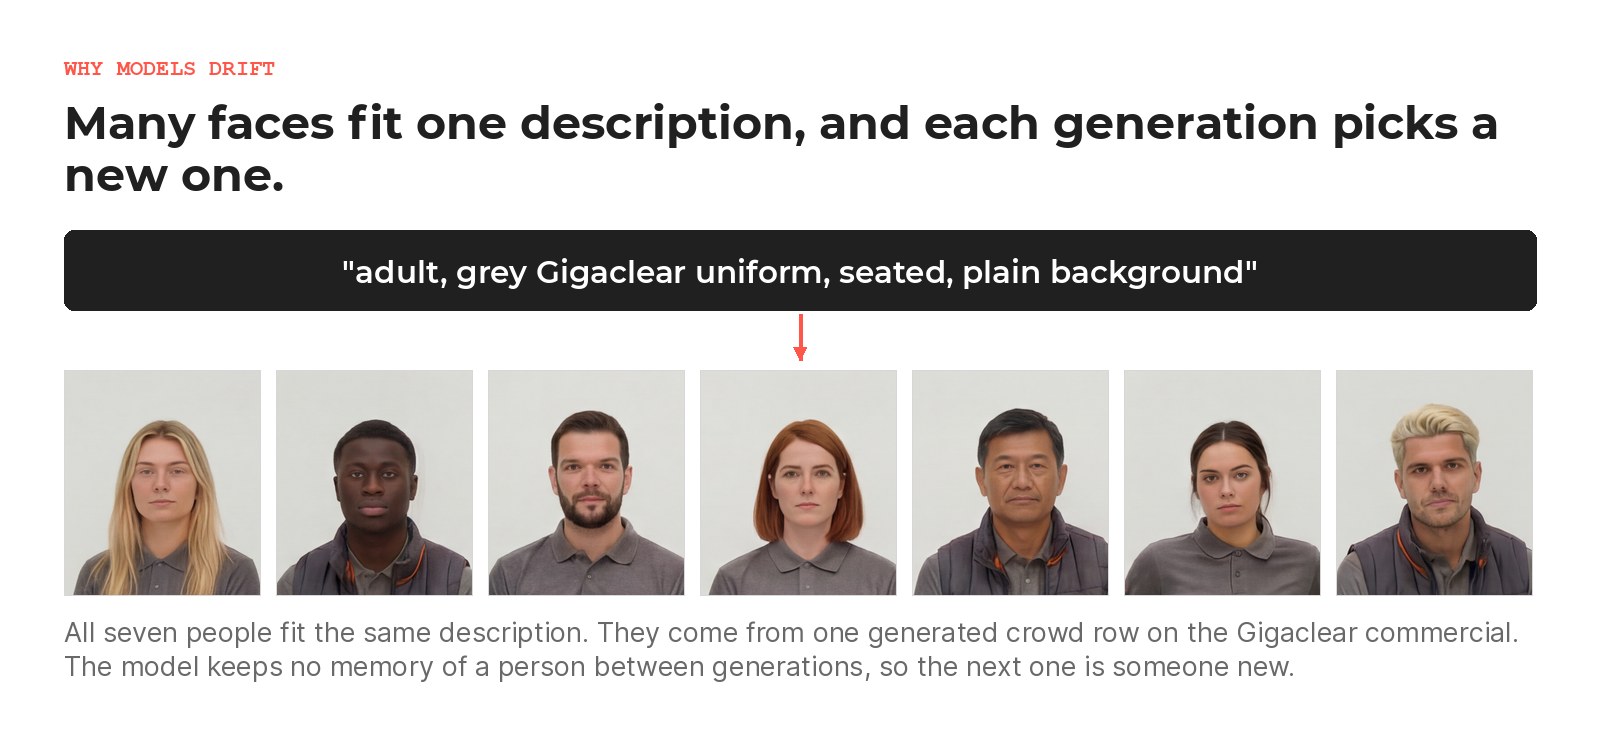
Ask AI for the same woman in a second shot and you get a different woman who fits the same description. The same thing happens to a bottle, a pack and a logo. That is what you want while you are exploring ideas, and it is what breaks a commercial, because a brand needs the same face, the same product and the same logo in shot 1 and in shot 40.
Writing a better description does not help. The decision that does is made before work starts: which things in the film may be generated, and which have to be built or supplied as the real thing. After reading this you can put that question to anyone offering AI production and judge the answer.
01 · The Drift
Why models forget what they just made
A diffusion model does not store your character. It stores a distribution, a statistical sense of how pixels tend to arrange into people, rooms and objects. Each generation is a fresh draw from it, nudged by your prompt and your seed, and nothing in the process carries an identity forward. So when you ask for the same woman in a new shot, the model invents a new woman who fits the same description. The description is coarse: "Thirty, red coat, dark hair" fits a million faces. What looks like forgetting is a model that had no memory in the first place.
02 · Two Kinds of Same
Look-consistency versus identity-consistency
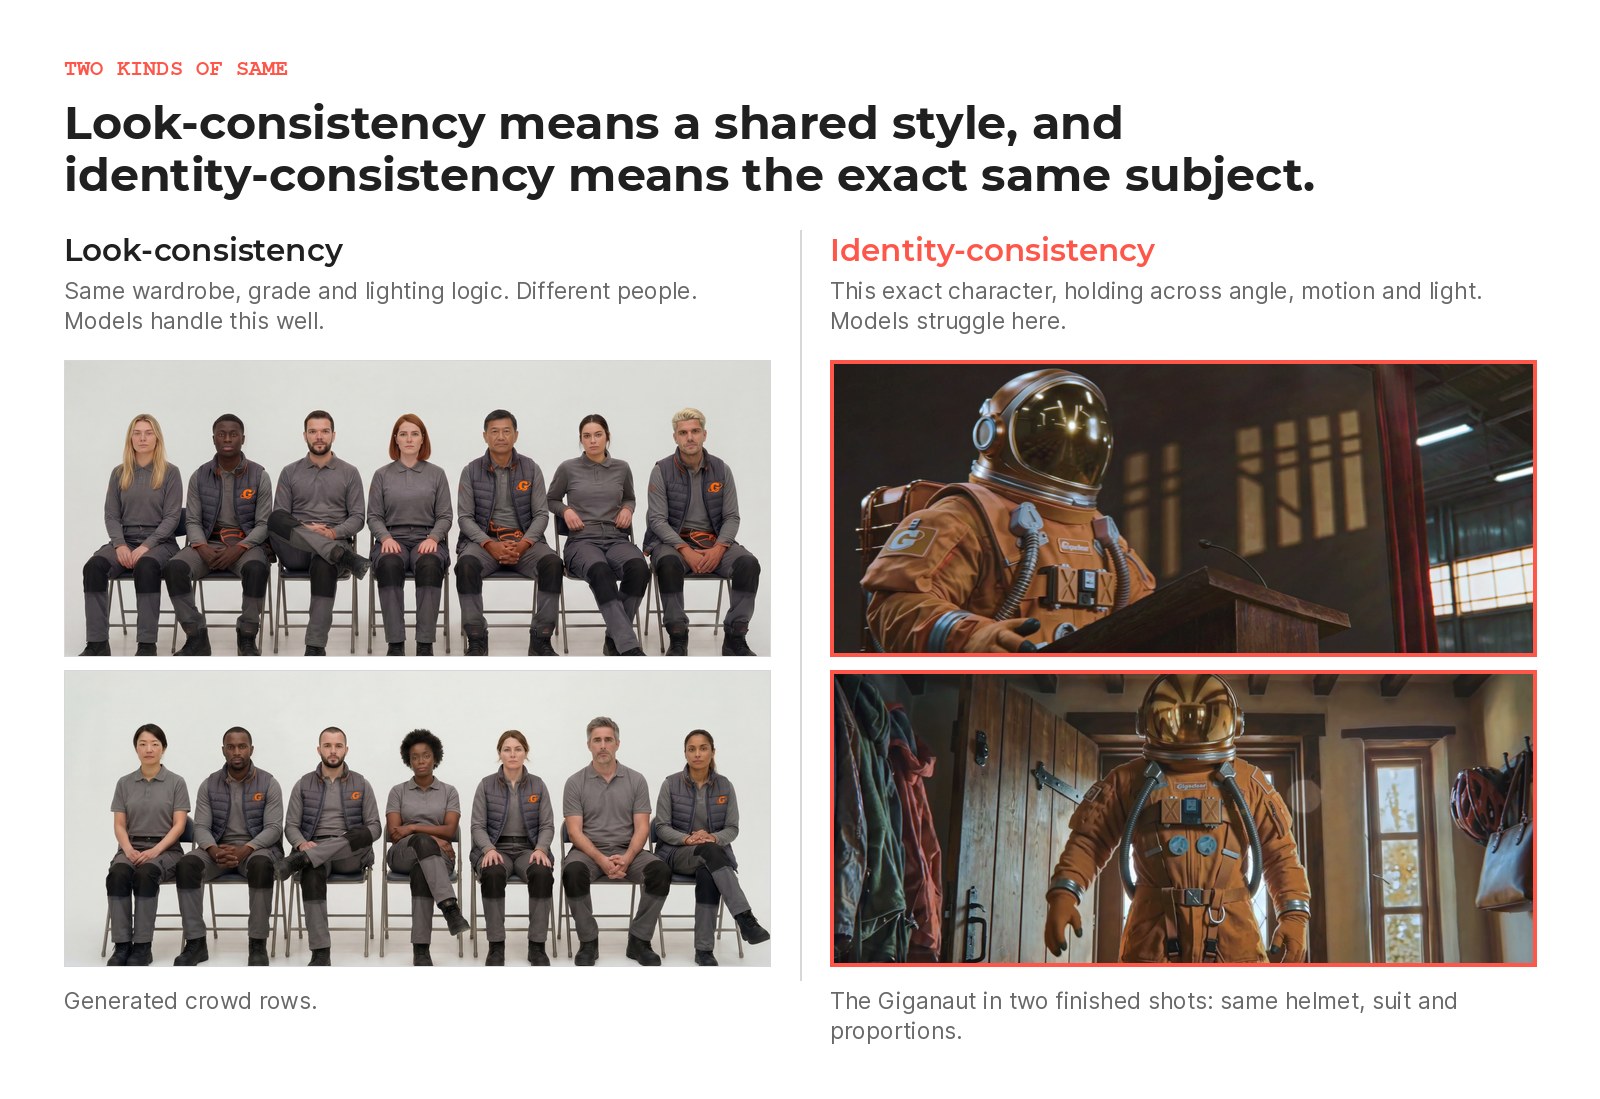
Two different things get called consistency. Look-consistency is the easier one: the same grade, grain, lens character and lighting logic across a sequence. That is largely prompt discipline, reference framing and colour work in the grade. Identity-consistency is the hard one: this exact person, this exact bottle, this exact wordmark, holding across changes of angle, motion and lighting. Models are reasonably good at the first because a "look" is itself a distribution, a mood, a palette. They are poor at the second because identity is a single point, and a model that samples a region will keep missing a point. Most consistency failures start with someone expecting look-consistency to deliver identity-consistency as well.
03 · The Toolkit
How far you can push generation
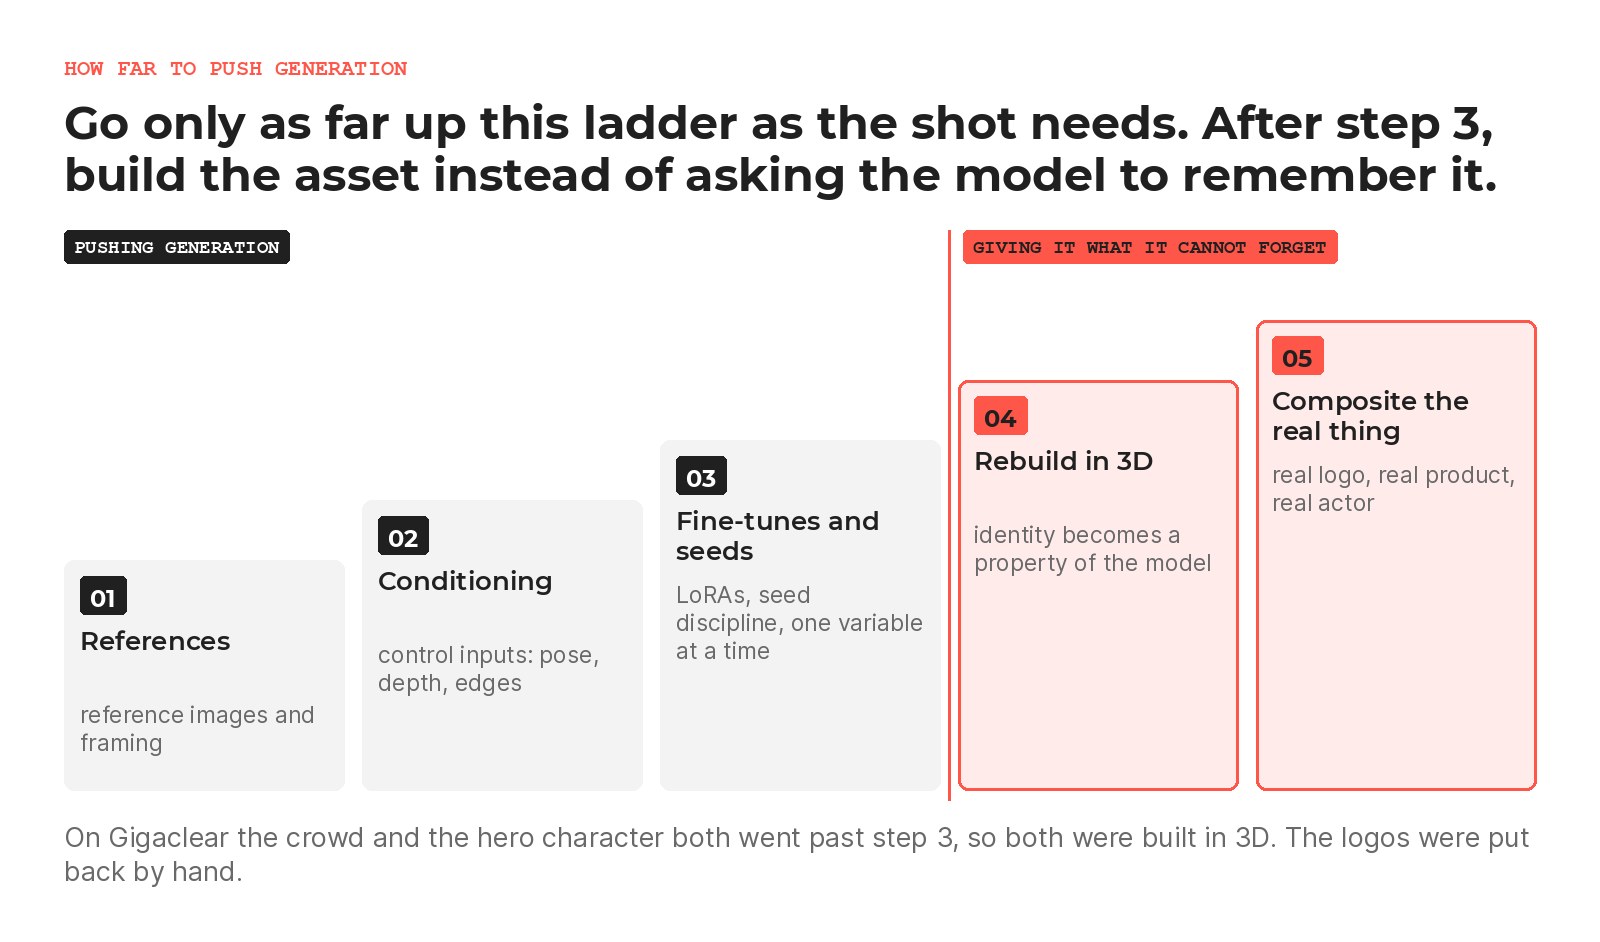
There is a ladder of ways to hold identity, and I climb it in order. Each rung costs more work than the one before, so I stop at the first rung that holds and move up as soon as one does not.
1. References
The approved face, product or character goes in as locked reference images, through reference inputs or an IP-adapter. That carries identity and look from one generation to the next. It weakens as the angle, the motion or the lighting moves away from what the references show, and that is the sign to go up a rung.
2. Conditioning
Control inputs fix the structure of the frame: pose from a skeleton, depth from a depth map, edges from a line render. With a fixed seed, the composition stops moving between runs. Conditioning holds layout and pose. Identity still depends on the references, so the two are used together.
3. Fine-tune or LoRA
When references and conditioning are not enough, I train a LoRA on the approved subject, so the model has learned that one character or product, and load it into the workflow. This narrows the model's guess a long way. It is still a guess, which is why fine detail such as lettering can keep wandering.
Those three rungs all push generation harder. Past them the method changes: the subject stops being generated and becomes something built or supplied.
4. Rebuild in 3D
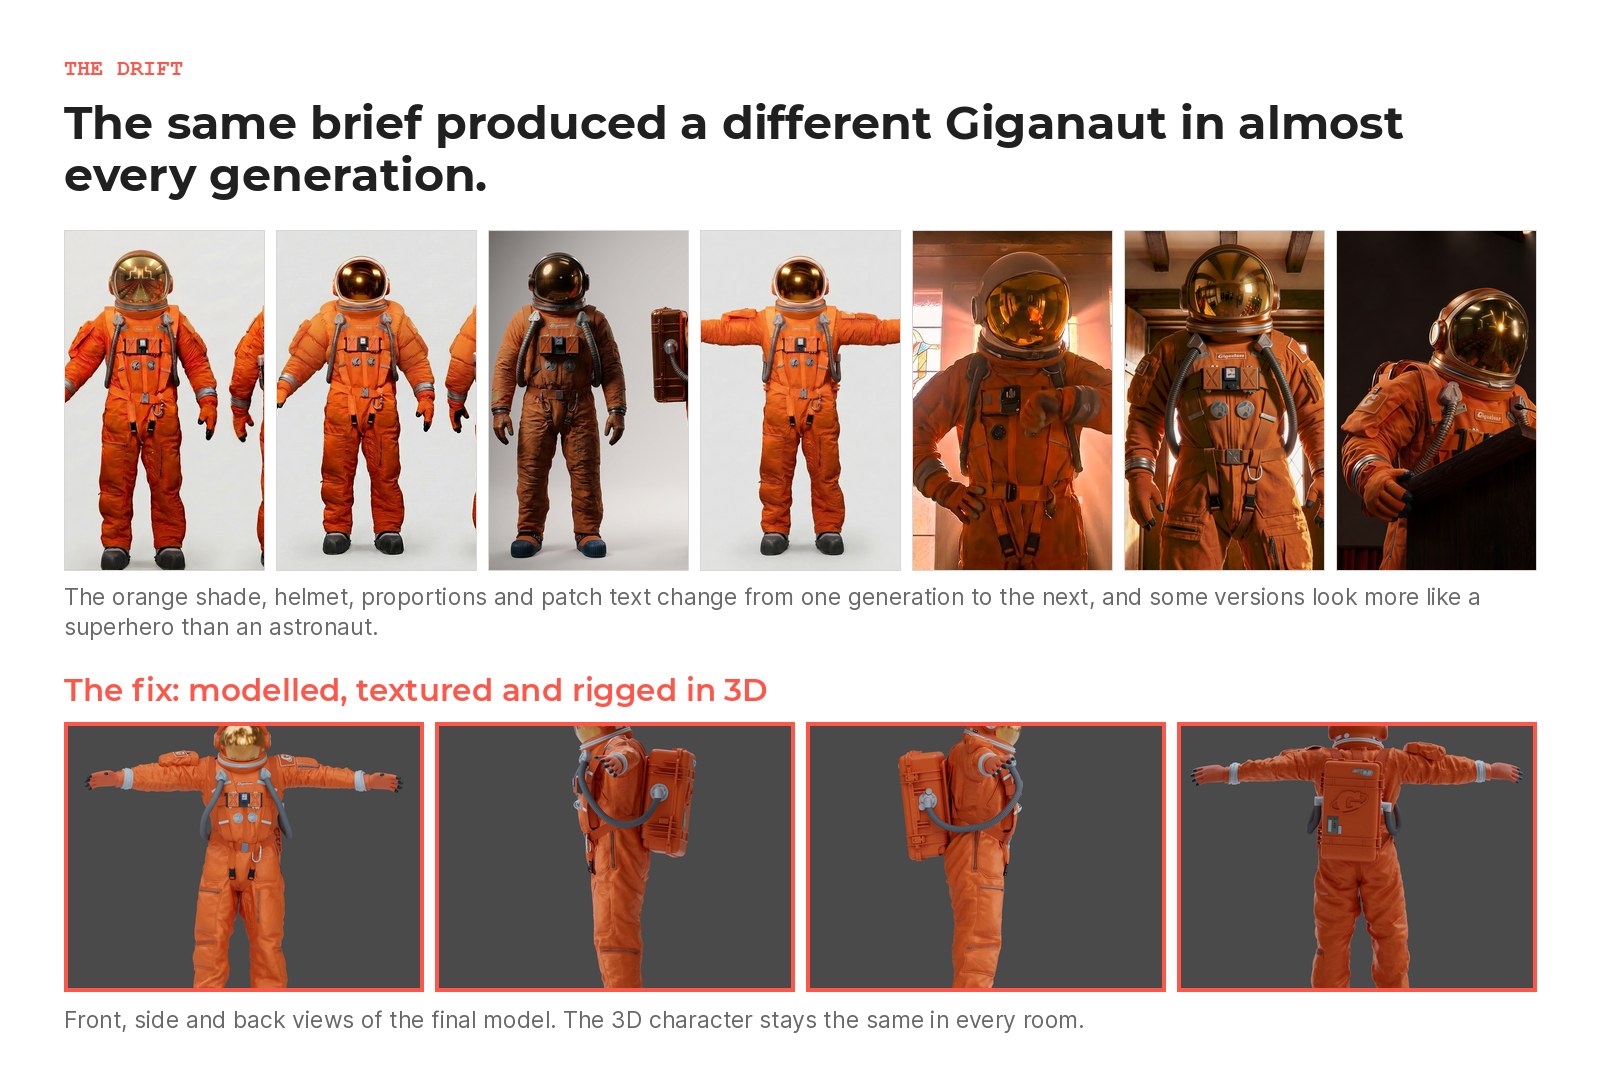
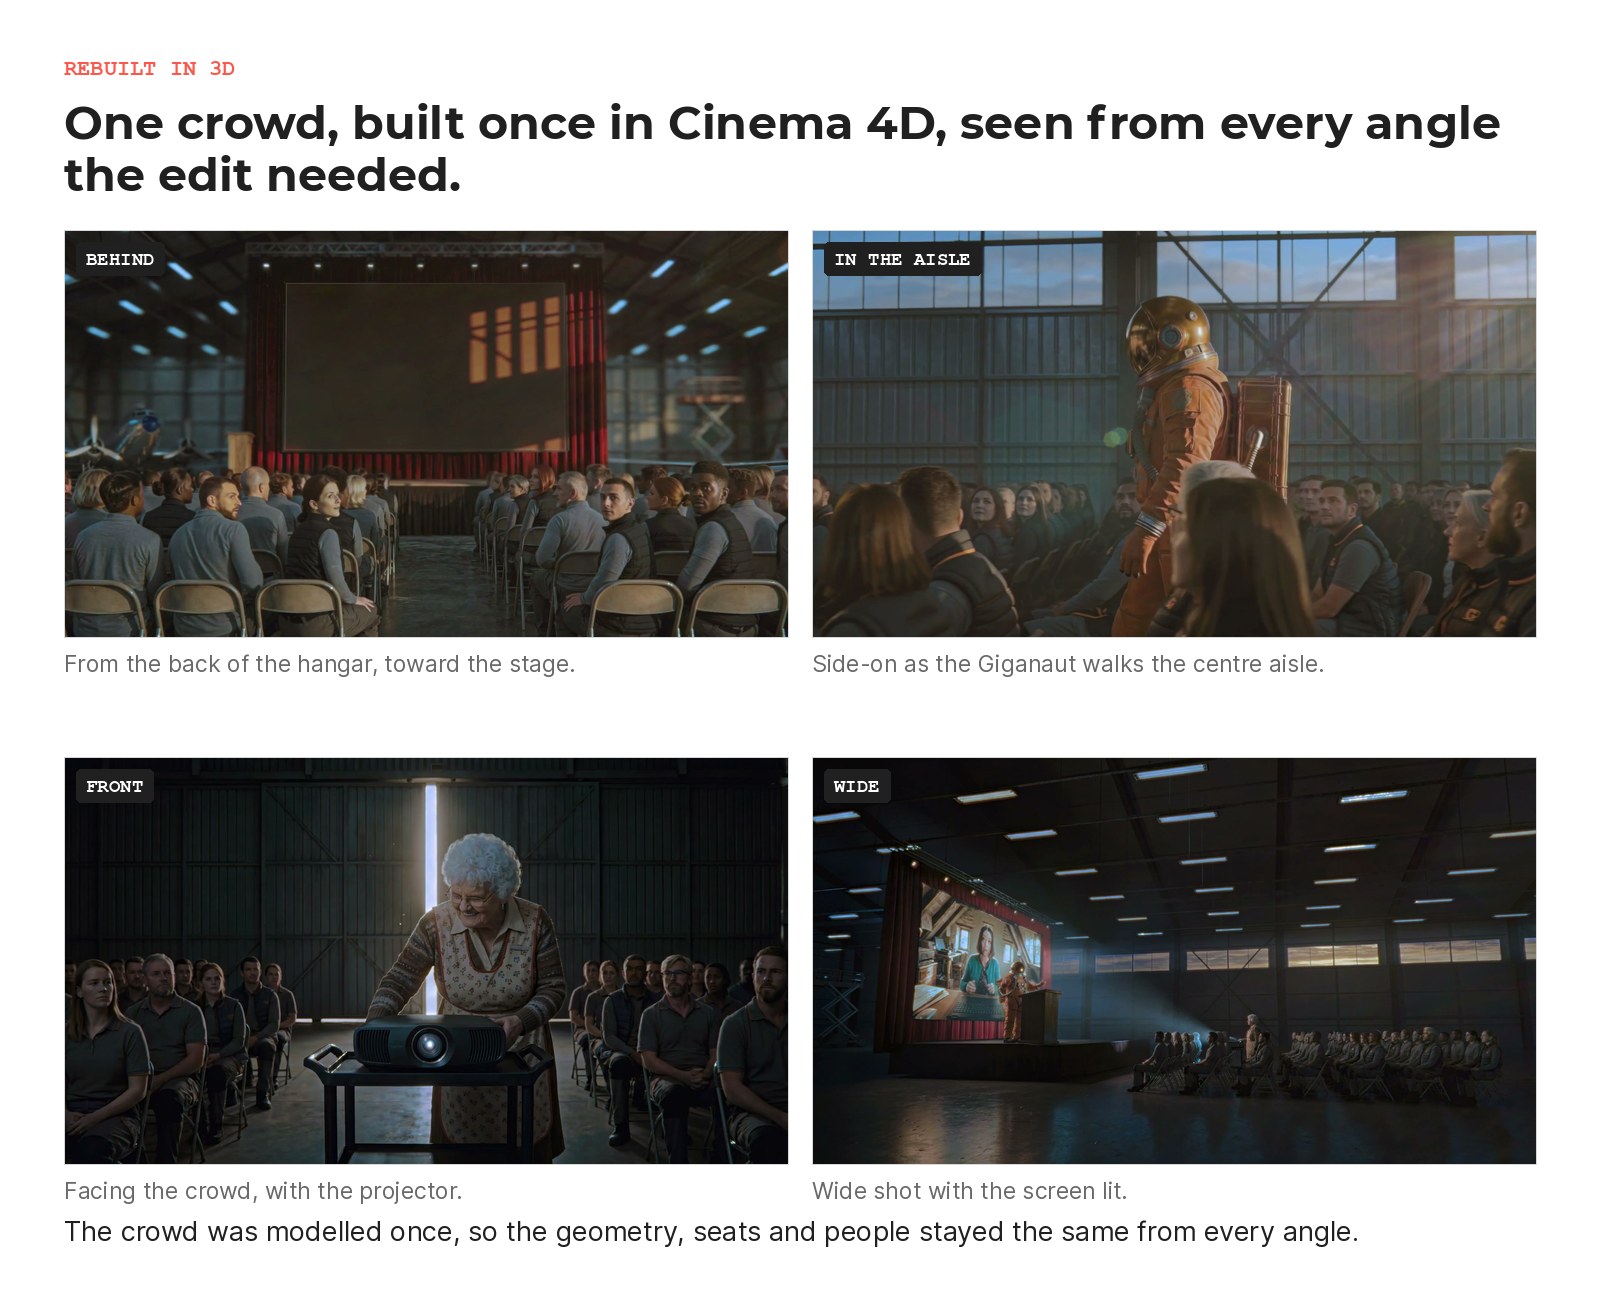
If the subject has to be the same from every angle, or there are too many identities to hold at once, it is built as geometry and the model generates on top of the render. Both the Giganaut and the Gigaclear crowd went this way. The next section covers the crowd.
5. Composite the real thing
Logos, packaging, on-screen text and real actors are supplied or filmed, then tracked into the shot in compositing. This rung involves no generation, so there is nothing to drift.
Each rung is a separate control in the workflow. I cover locking approved elements in a node workflow in its own article.
04 · When Generation Can't Hold It
Rebuild in 3D or composite the real thing
At some point it is better to stop asking the model to remember and give it something it cannot forget. On the Gigaclear national spot we needed a crowd of a hundred characters that stayed the same people across every angle of the edit. No amount of seed discipline survives a hundred identities through a camera move. So the crowd was built once in Cinema 4D: the same geometry and the same materials, viewed from wherever the shot required. The identity lived in the 3D scene, which is why it did not drift. Live actors were filmed and composited in over that base. That is the pattern. When generation cannot hold identity, the asset is rebuilt in 3D or a real element is composited in, and the generator becomes one layer of the shot.
05 · Products, Logos and Text
The things AI will not respect
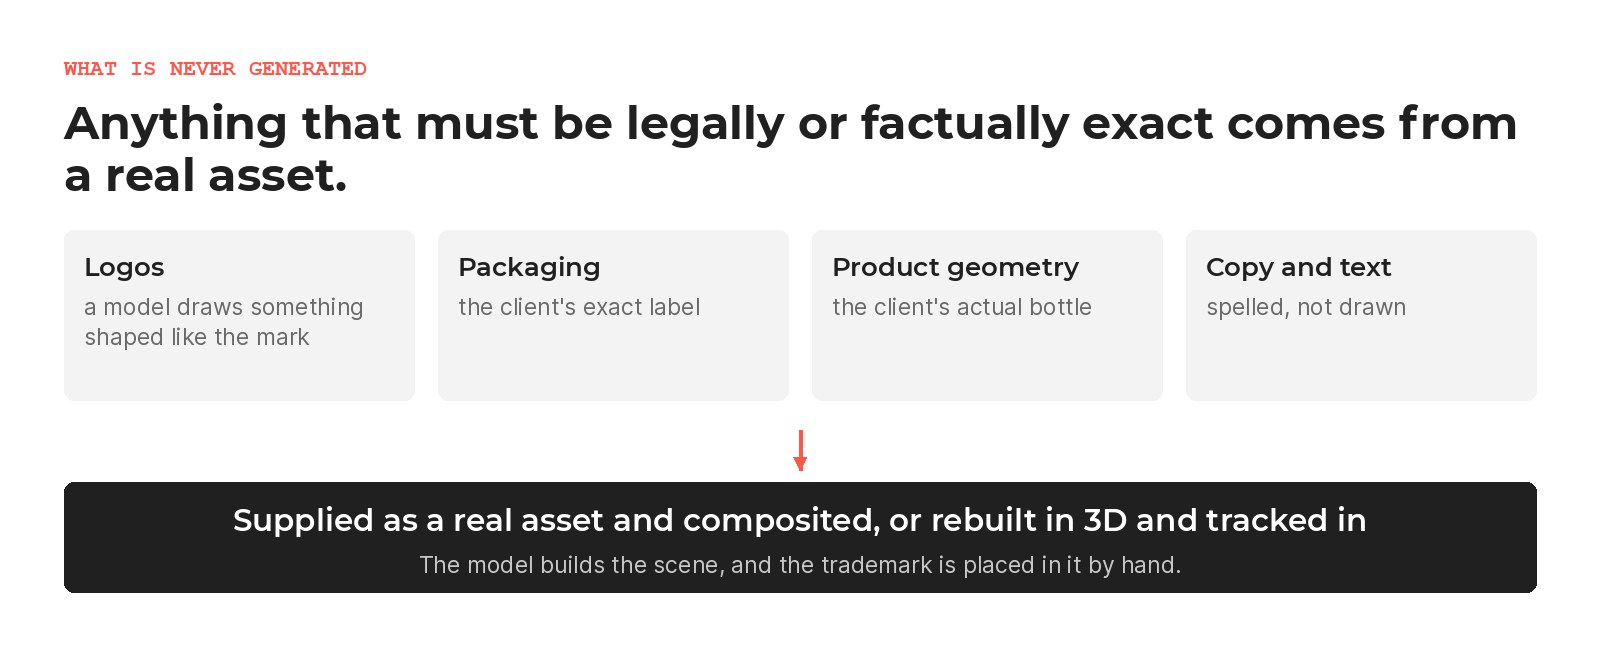
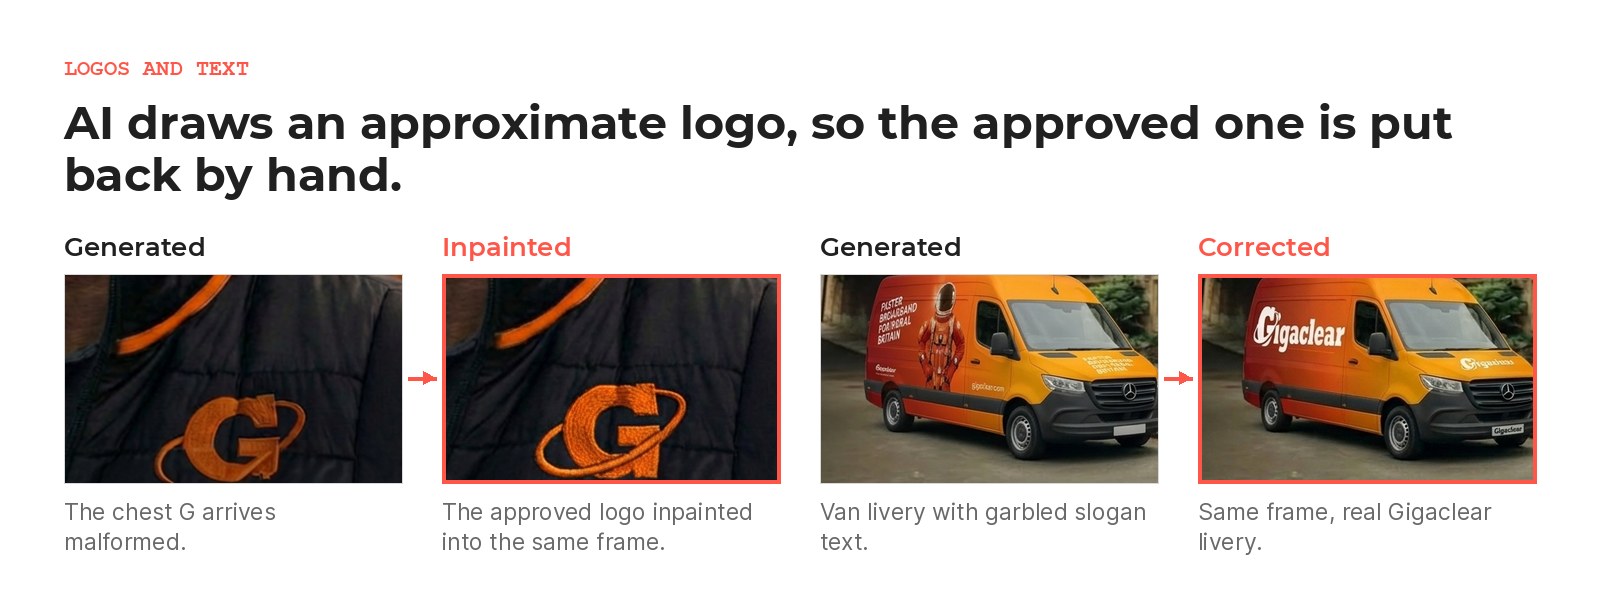
This is where you are most exposed and least warned. A product has to be exact: your bottle, your label, your trademark. A model has no concept of a trademark. It will render something in the neighbourhood of the logo, subtly wrong in proportion and kerning. Typography fails for the same reason: the model draws the shape of text without spelling it, so a tagline arrives as convincing gibberish. The rule I work to: anything that must be legally or factually exact (logo, packaging, product geometry, copy) is not generated. It is supplied as a real asset and composited, or rebuilt in 3D and tracked in. The model makes the world, and the trademark is placed into it by hand. The VFX article shows how real logos and text are tracked back in.
If you are buying AI production, ask the vendor one question before you start: which elements will be generated, and which will be supplied and composited?
06 · A Pipeline Problem
The useful part is the system around the model
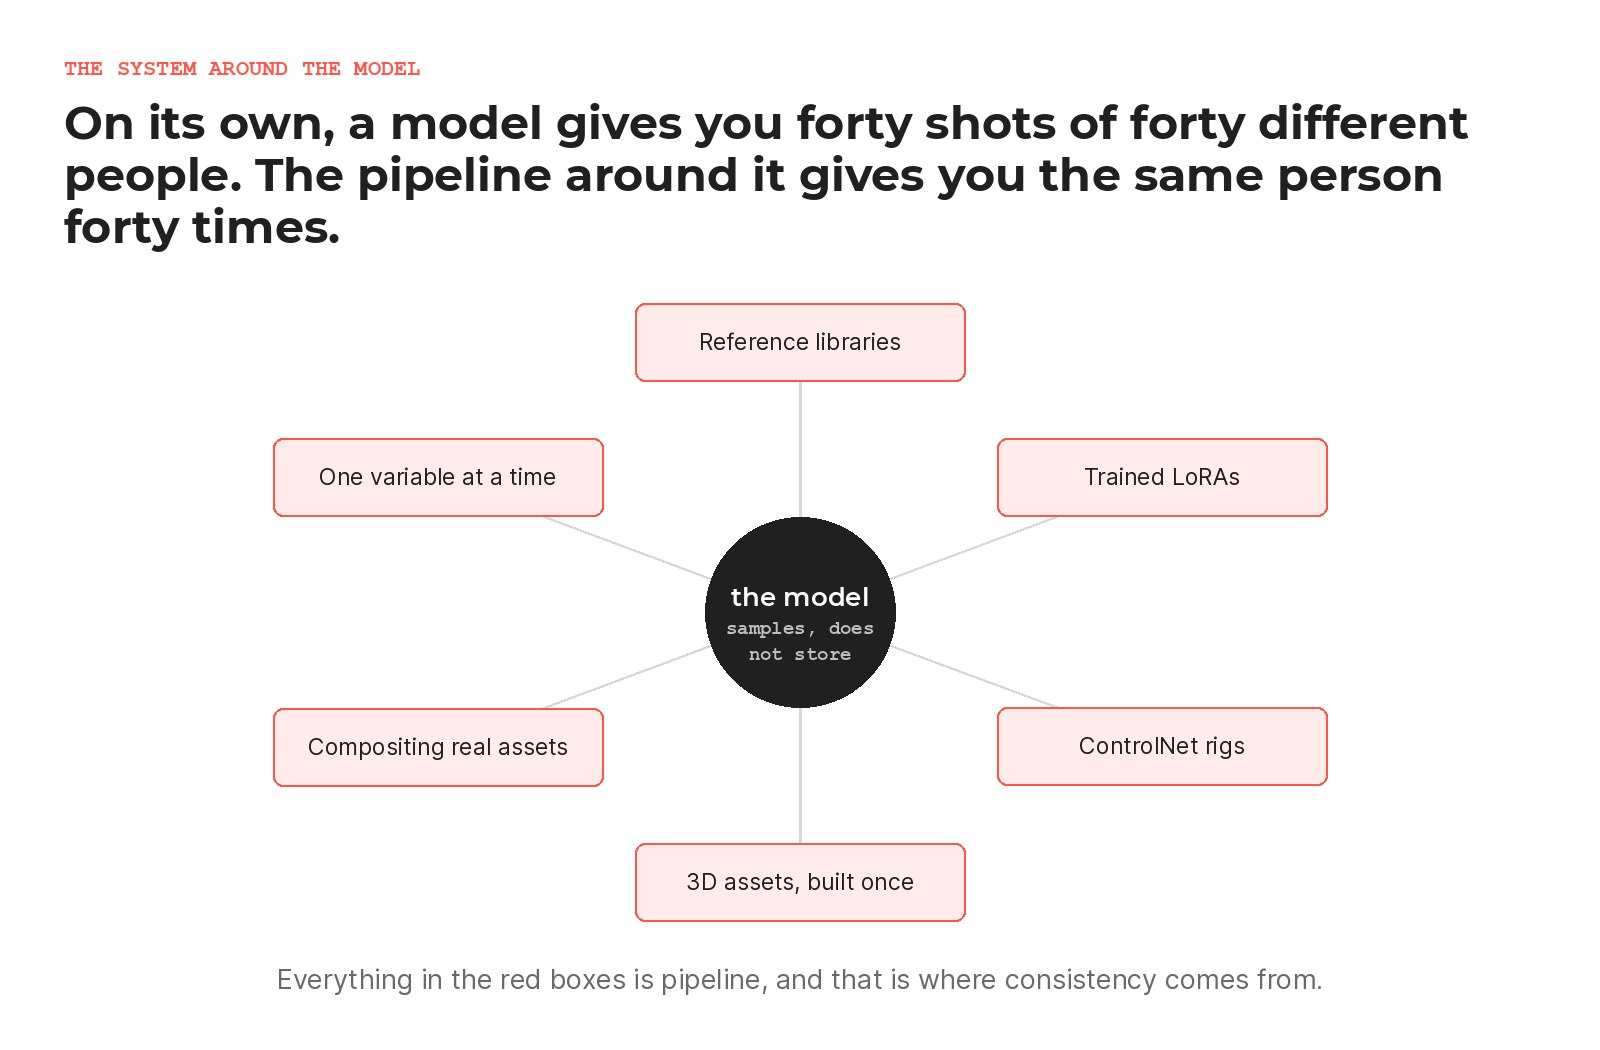
Consistency cannot be prompted into a film, because the model samples and does not store. It is won in the system around the model: the reference libraries, the trained LoRAs, the ControlNet rigs, the 3D assets built once and reused, the compositing stage where real logos and real faces are laid back in, and the discipline of changing one variable at a time. A model on its own will give you forty beautiful shots of forty different people. A pipeline gives you the same person, forty times.
The system has limits too. Generated shots get harder to hold the longer they run, hands are the first thing to change between frames, and a logo can morph as the camera passes it. Those are the shots I move to 3D or compositing first.
Frequently Asked Questions
Why does AI video change the character between shots?
Models sample fresh every time. They are built to reinvent and keep no memory of the last shot. That drift is fine for exploring and fatal for a brand that needs the same face in every shot.
How do you keep a character consistent in AI video?
With the system around the model: locked identity references and control inputs first, then a trained LoRA. When generation still can't hold it, the subject is rebuilt in 3D or real footage is composited in.
Can AI keep a product or logo accurate?
Not on its own. Logos, packaging and text are supplied as real assets and composited or tracked in, so the brand asset stays exact.
What's the difference between look-consistency and identity-consistency?
Look-consistency is a matching style or mood. Identity-consistency is the same face or product every time. Commercials need the second, and it is the harder problem.
Send the script or the deck. Within a day you get a written reply: what is realistic and how I would make it. That first read is free, and if AI is not a fit I will say so.
Send the brief → See how the Gigaclear commercial was made →